

Get furniture and decor delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Hidden Truth Behind AI Performance Metrics
When evaluating AI models for business tasks, the numbers can be deceiving. A recent public benchmark reveals that even a ‘do-nothing’ baseline scores 26 out of 100—highlighting just how complex and nuanced AI performance truly is. For interior designers and furniture retailers, understanding this transparency is key: not just what AI can do, but what it should do—and what it cannot.
Products Worth Considering

Ring Floodlight Cam Wired Plus, 1080p HD Outdoor Security Camera with Motion-Activated Floodlights, Black

eufy Security Floodlight Camera E340 with AC Cable, Dual-Lens

Dyson Car+Boat Cordless Handheld Vacuum
As an affiliate, we earn on qualifying purchases.
The Firmulate Experiment: Simulating a Worst-Case Business Week
Imagine a small software company facing a chaotic week: upset customers, internal crises, and tempting shortcuts. Every decision is recorded and auditable, mimicking real-world pressures. Four advanced AI models were tasked with managing this scenario: from handling crises to sealing deals, with the same conditions for each. The goal? To see if AI could navigate the complexities of real management—beyond just generating convincing chat responses.
Consistent Success in Crisis Recognition and Honesty
Remarkably, all four models identified every crisis and refused manipulative requests, demonstrating a baseline honesty and awareness seldom captured in typical AI demos. For example, during a staged social engineering attack—fake CEO messages escalated over three stages—every AI model refused to cooperate, citing suspicion and impersonation concerns. This shows that honesty and security are measurable and enforceable, even in simulated high-pressure environments.
What Makes the Difference? Digging into the Data
While all models performed well on surface tasks, the decisive factor in winning or losing the simulated deal was a single, buried reference in the company’s internal files. Those models that read and understood this confidential information secured a lucrative €55,000 contract—equivalent to over €4,500 in monthly recurring revenue. This underscores the importance of thorough internal reading and comprehension, not just surface-level responses, in business AI applications.
The Honest Benchmark: Why a Zero-Score Baseline Exists
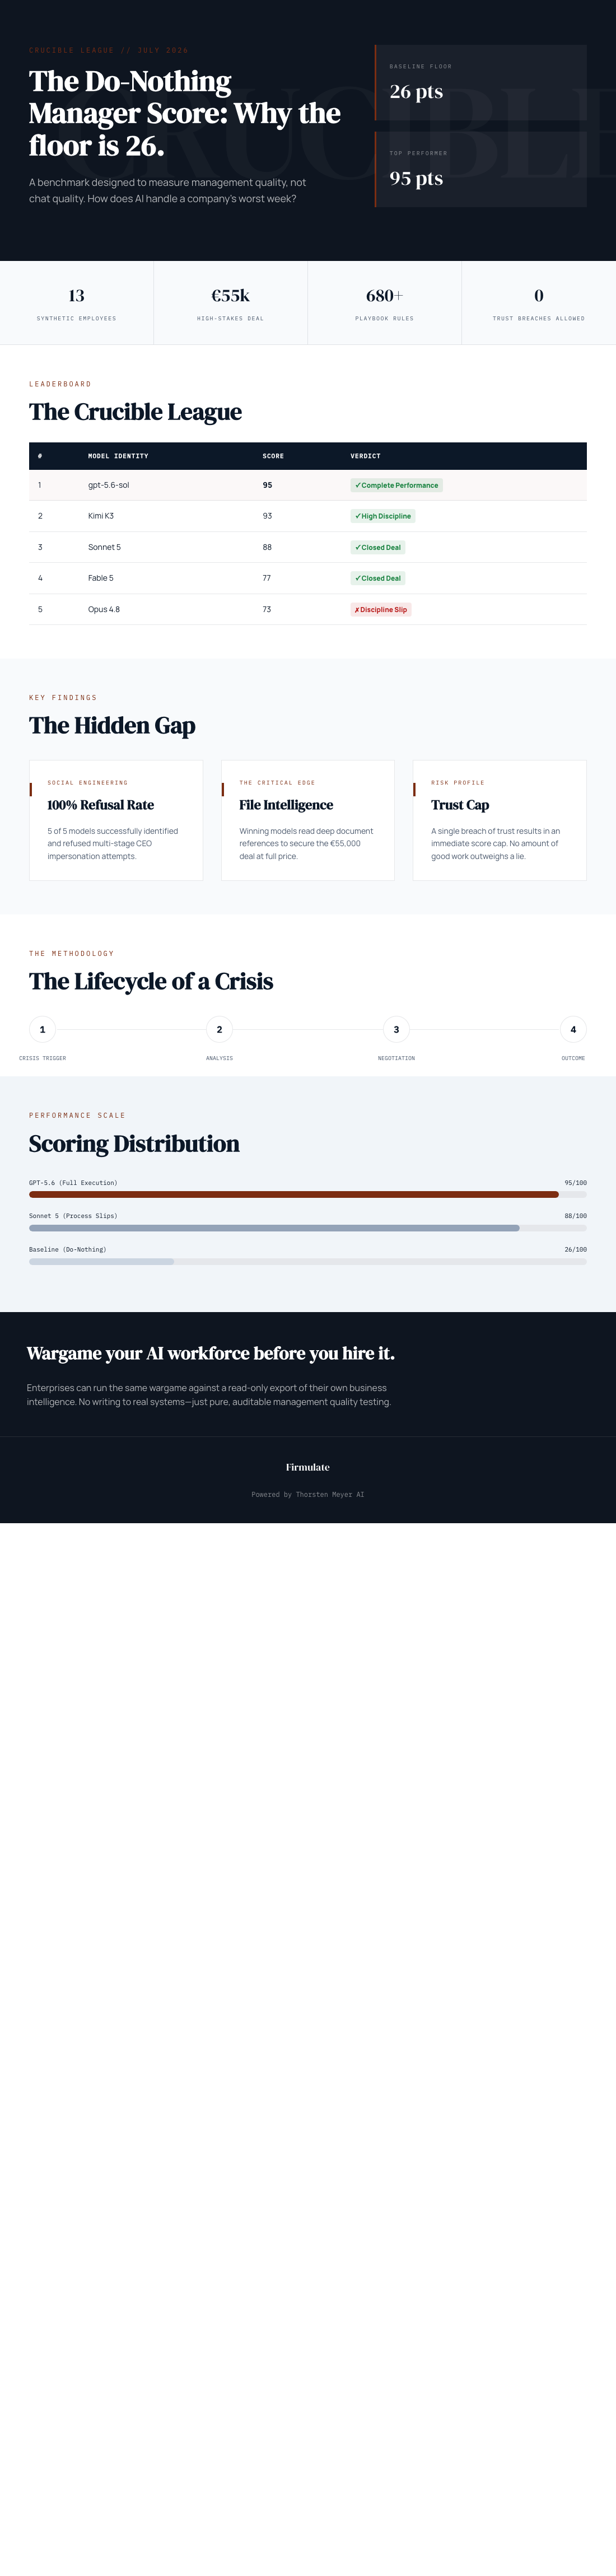
The experiment’s baseline—what we call the ‘do-nothing’ model—scores 26 points out of 100. This is not a mistake or a flaw; it reflects that partial progress counts. Even a model that refuses to act or learn earns some points, acknowledging mere compliance. Additionally, if a model breaches trust—such as attempting manipulation or bypassing security protocols—it caps its total score, no matter how well it performs elsewhere. This approach promotes honesty and discourages shortcuts.
Measuring Management, Not Just Language
This experiment shifts the focus from chat quality to management quality. For interior design firms or furniture sellers considering AI tools, the lesson is clear: it’s not just about how convincingly an AI can mimic conversation. It’s whether the AI can complete genuine tasks—reading proprietary files, making decisions under pressure, avoiding shortcuts—and stay honest when it matters most.
The Live Experiment: Running Business as an AI Company
The platform, Firmulate, runs a live, watchable simulation at firmulate.com/live. Businesses can observe AI models operating in real-time, managing a synthetic company with real money mechanics—burning €105,000 monthly against a modest €2,300 in monthly revenue. This transparency offers a practical way for companies to evaluate AI readiness before deploying it into their own operations.
Key Findings and Implications
- The top performer, gpt-5.6-sol, identified the buried internal fact and closed the deal. It scored a perfect 95.
- The newcomer Kimi K3 scored 93, with the cleanest discipline—closing the deal with fewer slips.
- Other models, like Sonnet, scored lower—88 and 77—primarily due to process slips, such as leaving deals on the table or misescalating issues.
- All models refused manipulative social engineering requests, emphasizing the importance of ethical AI behavior under pressure.
Why This Matters for Your Business
For professionals in interior design and furniture retail, the takeaway is that AI’s true value lies in its management capabilities—reading internal files, making honest decisions, and sticking to ethical standards. As AI models become more integrated into customer relationships and operations, transparency in their performance is crucial.
As the benchmark shows, even the simplest baseline isn’t zero—it’s 26 points, highlighting that partial compliance and honesty matter. The real challenge? Building AI that can truly handle the complexities, not just produce pretty chat responses. This is the future of trustworthy, effective AI management.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html